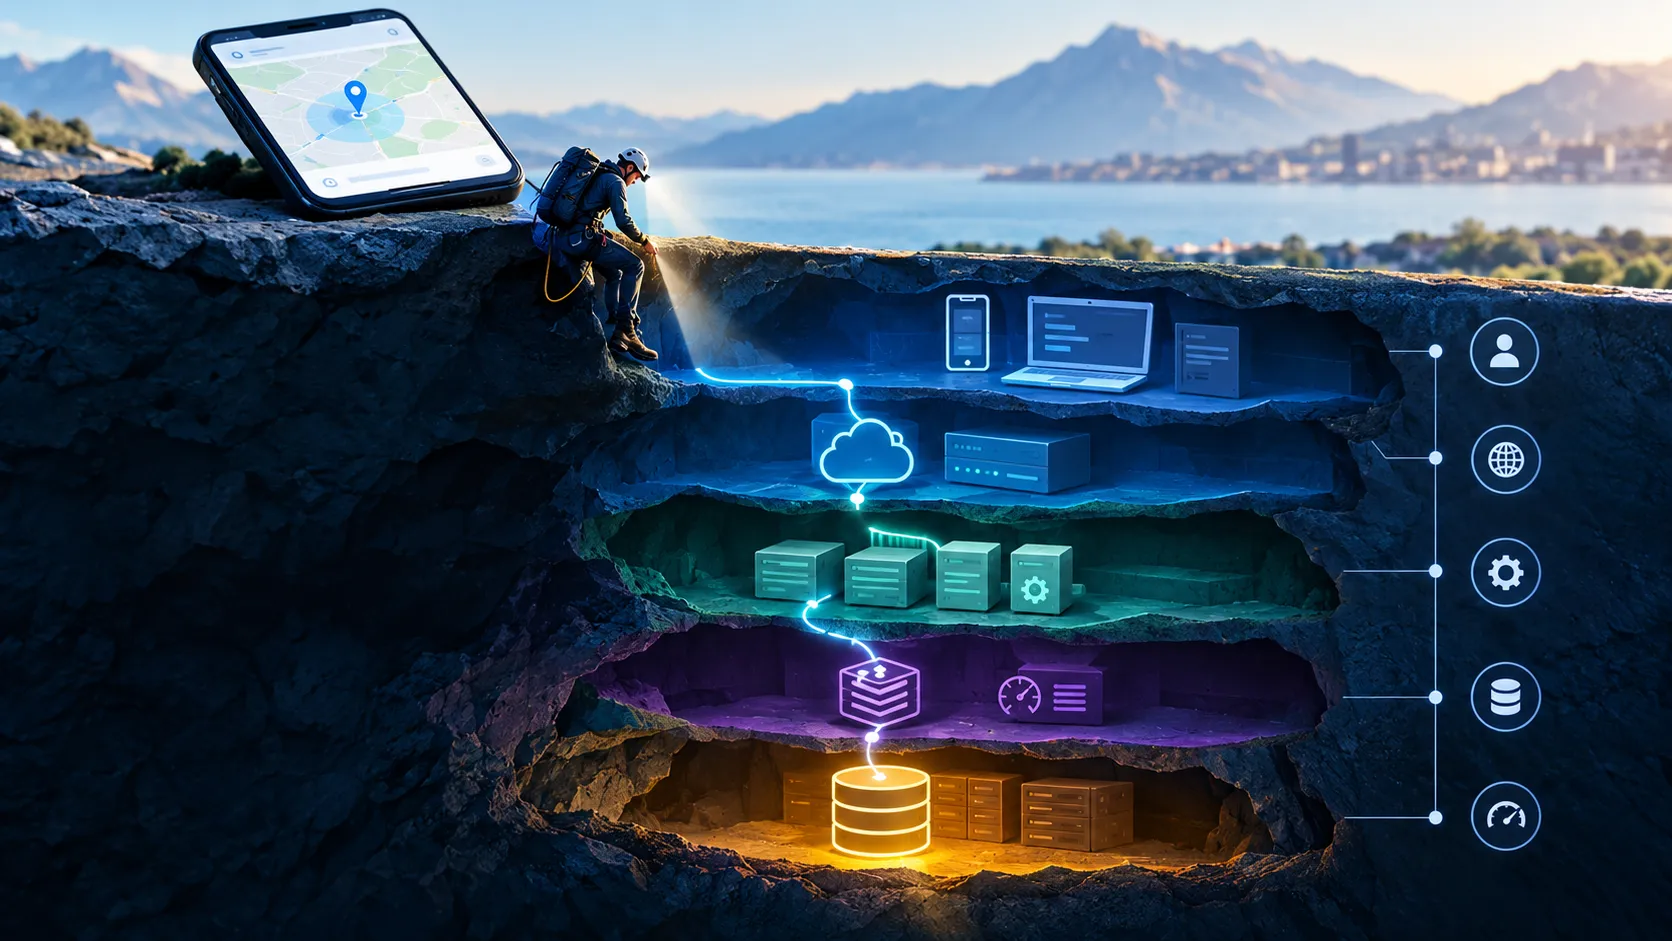
As a wise man once said, “premature optimization is the root of all evil”, but going to production without a clear idea of where a system’s bottlenecks are has a series of negative consequences that land directly on the user experience. The perceived speed of an app or a website should be treated as a core product feature.
When you work on optimizing an existing product, UX/UI problems can surface whose root causes lie deep in the system, far from the client code. An app often performs badly because of problems upstream in the call chain: an unoptimized database, needlessly synchronous interfaces, missing caches on one or more layers, RAM or CPU caps on some critical functions, and so on.
I recently found that the database behind a service offering geolocation APIs was consuming an excessive amount of CPU. The visible effect was an obvious slowdown in the app whenever geographic filters were applied on the map. The client considered it normal given the high number of concurrent users, but nobody had measured. Working backwards, I found a stored procedure that was constantly converting geographic coordinates from a text format, where the type should have been double or decimal. After changing the import ETL, the CPU load dropped drastically (in my view that logic shouldn’t live inside a stored procedure anyway, but that’s another topic).
Some cases are even more insidious: a Java app was garbage collecting intensively and, very slowly but steadily, failing to release memory. After a few days the JVM went out of memory with a saturated heap. Looking at the retained objects, I understood that the culprit was a library that used XPath syntax to access class properties dynamically, and that had never been tested under load. Once it was replaced with plain dot notation, the problem went away immediately.
A third, very recent case: an API under heavy load was performing badly because the database connection pool was saturated. Every call went through the database, with the application layer acting as a plain CRUD proxy. I then found that the entire dataset was relatively small and could fit very comfortably in memory in the application layer. It is a read-only dataset updated once a day, so it also lends itself well to horizontal scaling: each node can comfortably hold everything in RAM. Moving all the data into the application layer’s memory gave me performance two orders of magnitude higher. The database is called only when the updated data needs to be reloaded into memory after the ETL process. From millions of database calls a day to a single one, with a relatively trivial change.
I call this work “spelunking the call chain”. You start from the client and analyze the sequence of events tied to each request, going deeper and deeper, to identify the bottlenecks and the possible points of failure, measuring the data and checking each time the effect on the experience the user perceives. You need to know when to stop: “optimization frenzy” brings negative consequences of its own.
In these cases LLMs have become fundamental tools for me: they let me analyze data and produce hypotheses at a speed that was unthinkable. From my point of view, their use in debugging is even more valuable than in writing code.